LearningPaper24 2025
Presentation videos and paper metadata for video understanding and summarization.
- conference talks
- 2,287
- all-time downloads
- 10,404 As of Oct 08, 2026
I am a final-year Ph.D. student in Computer Science at the University of Texas at Austin, advised by Ufuk Topcu. Previously, I earned my B.S. in Computer Science and Mathematics at the University of Virginia, advised by Lu Feng.
I develop AI agents that collaborate with people under incomplete information and human cognitive limits. As agents become more capable, people still provide incomplete guidance and have limited attention to review their decisions. My research addresses both sides of this exchange: how agents infer human intent, and what information they should communicate to support human decisions.
My research spans the following topics:



* Equal contribution.
See the complete list of publications.
Presentation videos and paper metadata for video understanding and summarization.
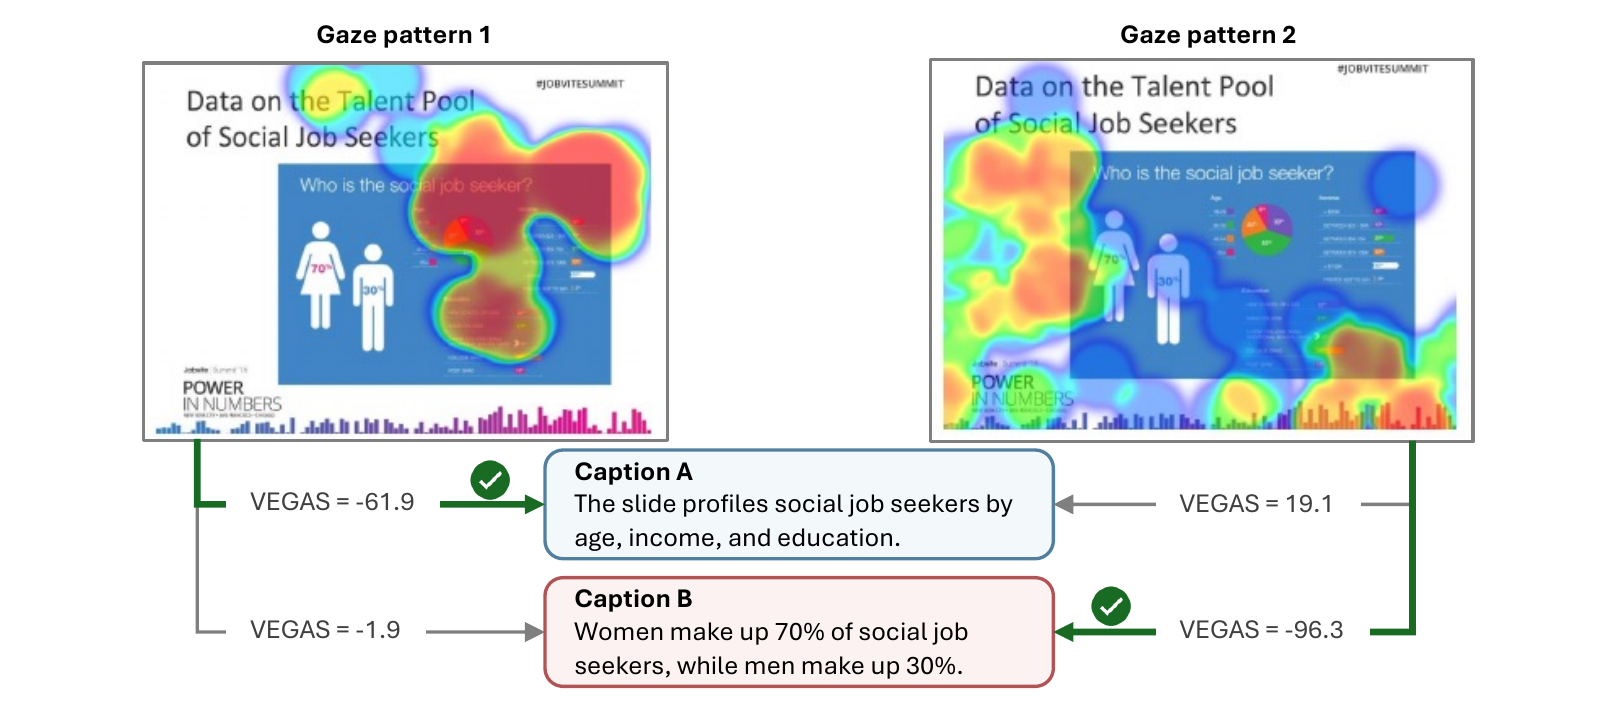
Egocentric activities and instructional slides paired with synchronized gaze and reference annotations for attention-aligned video caption evaluation.
Public download currently unavailable.
Explore the datasets.
Our paper VEGAS: Human-Aligned Video Caption Evaluation via Gaze has been accepted to Transactions on Machine Learning Research (TMLR)!
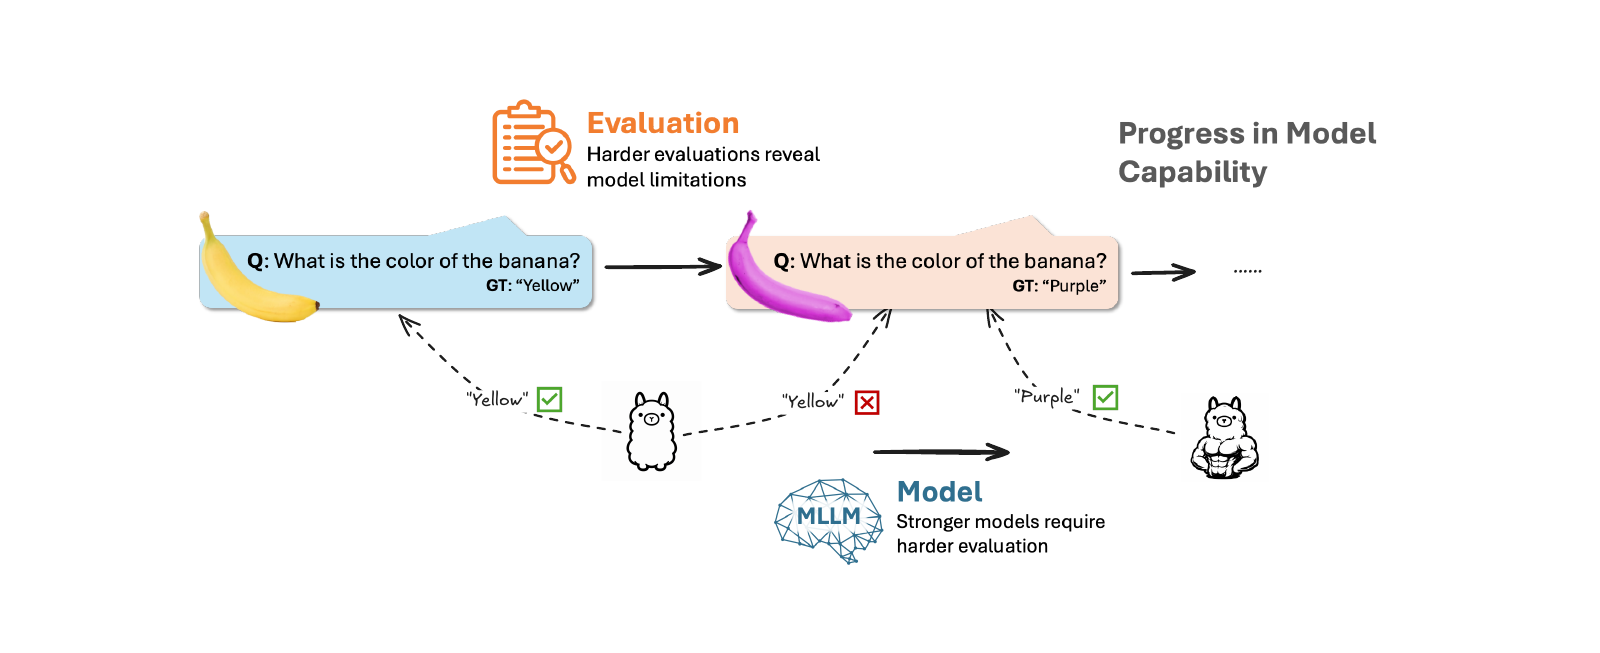
Our paper What We are Missing in Multimodal LLM Evaluation?, with Po-han Li, Sandeep Chinchali, and Ufuk Topcu, has been accepted to Communications of the ACM!
Participated in the Asian Deans’ Forum (ADF) Rising Stars Women in Engineering Workshop at HKUST, Hong Kong. Read my workshop recap and photos.
Invited talk to Prof. Mykel Kochenderfer’s group, SISL, at Stanford University.
Invited talk to Prof. Amy Pavel’s group at UC Berkeley.
Invited talk at Prof. Changliu Liu’s Intelligent Control Lab at Carnegie Mellon University.
Wrapped up a rewarding internship with AMD’s GenAI group.
Glad to be shortlisted for the ADF 2025 Rising Stars Asia program, see here.
Our paper on annotation-free video-to-text evaluation has been accepted to NeurIPS 2025! Learn more on our project page.
Check out our new preprint on annotation-free video-to-text evaluation, introducing VIBE to select captions as human-centered TL;DRs
Presented at the AIML Seminar, University of Virginia on title “Human-Agent Collaboration under Incomplete Information: Intent, Communication, and Planning”
Presented at the NSF CPS Frontier Site Visit, Purdue University on title “Human-Agent Coordination in Games under Incomplete Information via Multi-Step Intent”